
Interfaze 1.1 Lite: The Truly Open Weight Model for Deterministic Work
copy markdown
Most models you can call today were trained to write for a person. Interfaze 1.1 Lite writes for your code, and it puts a box and a confidence score on the text it reads.
Every model inside 1.1 is under a license that allows commercial use. This release also adds a new document reader and guardrails that check text safety in 119 languages.
What Lite does
Lite takes text, images, audio and files, including PDFs and Word documents, and returns text or JSON that matches your schema. It's meant for jobs with one right answer:
- OCR with a box and confidence for every line and word
- Speech-to-text with speaker diarization
- Classification and structured extraction into your schema
- Object detection and GUI detection
- Translation, forecasting and guardrails
The weights are open and the whole model runs on a single 80 GB GPU. Through the API it's $0.85 per million input tokens and $1.50 per million output tokens.
| Interfaze 1.1 Lite | |
|---|---|
| Input price | $0.85 / MTok |
| Output price | $1.50 / MTok |
| Context window | 128k tokens |
| Max output tokens | 32k tokens |
| Input | Text, images, audio, files |
| Output | Text, JSON |
| Reasoning | Available |
| PDF pages | Up to 50 per request |
| Open weights | Yes, runs on one 80 GB GPU |
| License | Apache 2.0, MIT and CC BY 4.0, commercial use allowed |
What's new in 1.1
1.1 replaces two of the specialist models. The API, the price and the one-GPU footprint stay the same.
The new document reader supplies the text, reading order, tables and markdown for each page. The line detector still adds a box and a confidence score to every line.
The new guardrails model checks text safety in 119 languages and maps each violation to an S1 to S14 category code.
The whole bundle is open for commercial use. Our own code is Apache 2.0, and each sub-model whose weights ship in the repo is under Apache 2.0, MIT or CC BY 4.0, so you can self-host Lite in a commercial product without negotiating a separate license.
The architecture
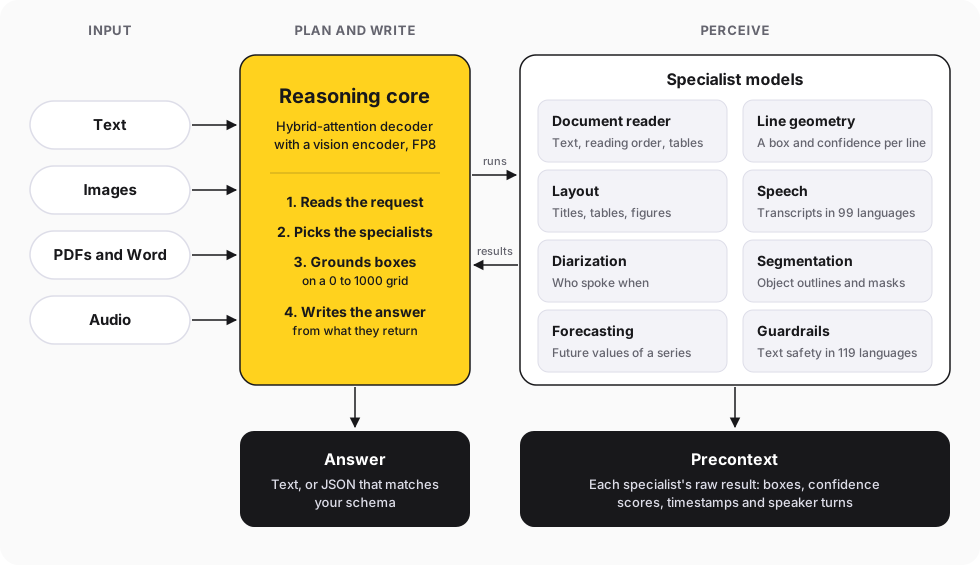
Lite is a reasoning core plus a set of specialist models, each built for one kind of perception.
The core reads the request, decides which specialists to run, and writes the answer from what they return. The specialists do the reading, listening and locating that a general model is weakest at.
Why split it up
A single vision-language model can read a page well. But like a person, it gives you the words without saying where they are on the page or how sure it was.
Specialists produce that metadata as part of how they work. A text detector scores every line it finds, and a speech recognizer timestamps every word.
| Approach | Reads the content | Exact positions | Confidence per line | Handles nuance |
|---|---|---|---|---|
| General VLM alone | Yes | Approximate | No | Yes |
| Specialist models alone | Yes | Yes | Yes | No |
| Lite: core + specialists | Yes | Yes | Yes | Yes |
The core understands the request, follows your schema and reasons about what it read. The specialists supply the precise output and the scores.
Everything the specialists produce comes back in precontext, so one response carries both the JSON answer and the evidence behind it.
Benchmarks
Here's Lite next to our flagship interfaze-1, GPT-5.4-Mini, Claude-Sonnet-4.6, Gemini-3-Flash and Grok-4.3. Bold marks the best score on each benchmark.
| Benchmark | Task | Interfaze 1.1 Lite | interfaze-1 | GPT-5.4-Mini | Claude-Sonnet-4.6 | Gemini-3-Flash | Grok-4.3 |
|---|---|---|---|---|---|---|---|
| MMMU-Pro | Multimodal reasoning | 73.2% | 71.1% | 40.4% | 46.3% | 67.6% | 68.7% |
| RefCOCO (Acc@0.5) | Visual grounding | 83.8% | 82.1% | 67.0% | 75.5% | 75.2% | 25.0% |
| SOB value accuracy | Structured output | 81.5% | 80.5% | 75.1% | 77.9% | 77.3%* | 78.4% |
| olmOCR-Bench | Document OCR | 83.8% | 85.7% | 80.1% | 73.9% | 75.3% | 81.9% |
| OCRBench V2 (English) | Text in images | 60.9% | 70.7% | 52.7% | 54.7% | 55.8% | 54.7% |
| VoxPopuli-Cleaned WER (lower is better) | Speech recognition | 3.01% | 2.4% | – | – | 4.0% | – |
| Spider 2.0-Lite (SQLite) | Text-to-SQL | 48.9% | 52.9% | 26.7% | 49.6% | 45.2% | 45.9% |
| GPQA Diamond | Graduate-level science | 85.9% | 92.4% | 82.8% | 89.9% | 88.5% | 73.6% |
| MMMLU | Multilingual knowledge | 87.8% | 90.9% | 75.3% | 84.9% | 88.7% | 89.7% |
Comparison scores are from the Interfaze leaderboard. A dash means the model has no speech recognition score. *Gemini-3-Flash-Preview.
Lite beats every third-party model scored on six of the nine: multimodal reasoning, visual grounding, structured output, document OCR, text in images and speech. It also beats our flagship on MMMU-Pro, RefCOCO and SOB, and it ranks second of 30 models on SOB.
It trails on text-to-SQL, science and multilingual knowledge, where interfaze-1 is the better pick.
See the full benchmark breakdown.
Self-hosting
The weights are on Hugging Face. The whole model runs on a single 80 GB GPU with no external services, so it works offline.
You need a GPU with compute capability 8.9 or newer, like an H100, and ffmpeg for audio.
hf download interfaze-ai/interfaze-1-lite requirements.txt --local-dir .
pip install -r requirements.txt
Load it with Transformers and call chat, the same entry point the API uses. The core plans, runs the specialists it needs and answers.
from transformers import AutoModel

model = AutoModel.from_pretrained("interfaze-ai/interfaze-1-lite", trust_remote_code=True)

answer = model.chat(
    [{"role": "user", "content": "What is the total, and which item is highlighted?"}],
    files=["receipt.jpg"],
)
print(answer["content"])
To skip planning, call one capability directly. ocr runs the document reader and line geometry and returns the stitched page.
doc = model.ocr("invoice.pdf", page_range=[1, 2])
print(doc["text"])
The model card covers every capability's method, arguments and output.
Transformers is slower than a batching serving engine. For throughput, use the API.
Use it with the Interfaze API
To try it without code, open the playground and pick Interfaze 1.1 Lite from the model picker. It shows the answer and the precontext behind it.
In code, set model to interfaze-1.1-lite. Structured output and precontext work the same as on every other Interfaze model.
Interfaze SDK
Vercel AI SDK
LangChain SDK
import { Interfaze } from "interfaze";

const interfaze = new Interfaze({ apiKey: process.env.INTERFAZE_API_KEY });

const response = await interfaze.chat.completions.create({
	model: "interfaze-1.1-lite",
	messages: [
		{
			role: "user",
			content: [
				{ type: "text", text: "Extract the details from this ID" },
				{ type: "image_url", image_url: { url: "https://r2public.jigsawstack.com/interfaze/examples/id.jpg" } },
			],
		},
	],
});

console.log(response.choices[0]?.message.content);
Interfaze speaks the Chat Completions standard, so any OpenAI-compatible SDK works too. Point it at https://api.interfaze.ai/v1 with your key from the dashboard.
Example: read an X-ray consult note
An orthopaedic clinic scans a consult note with the patient's ankle X-ray printed on it, and its records system needs the note as a typed record.
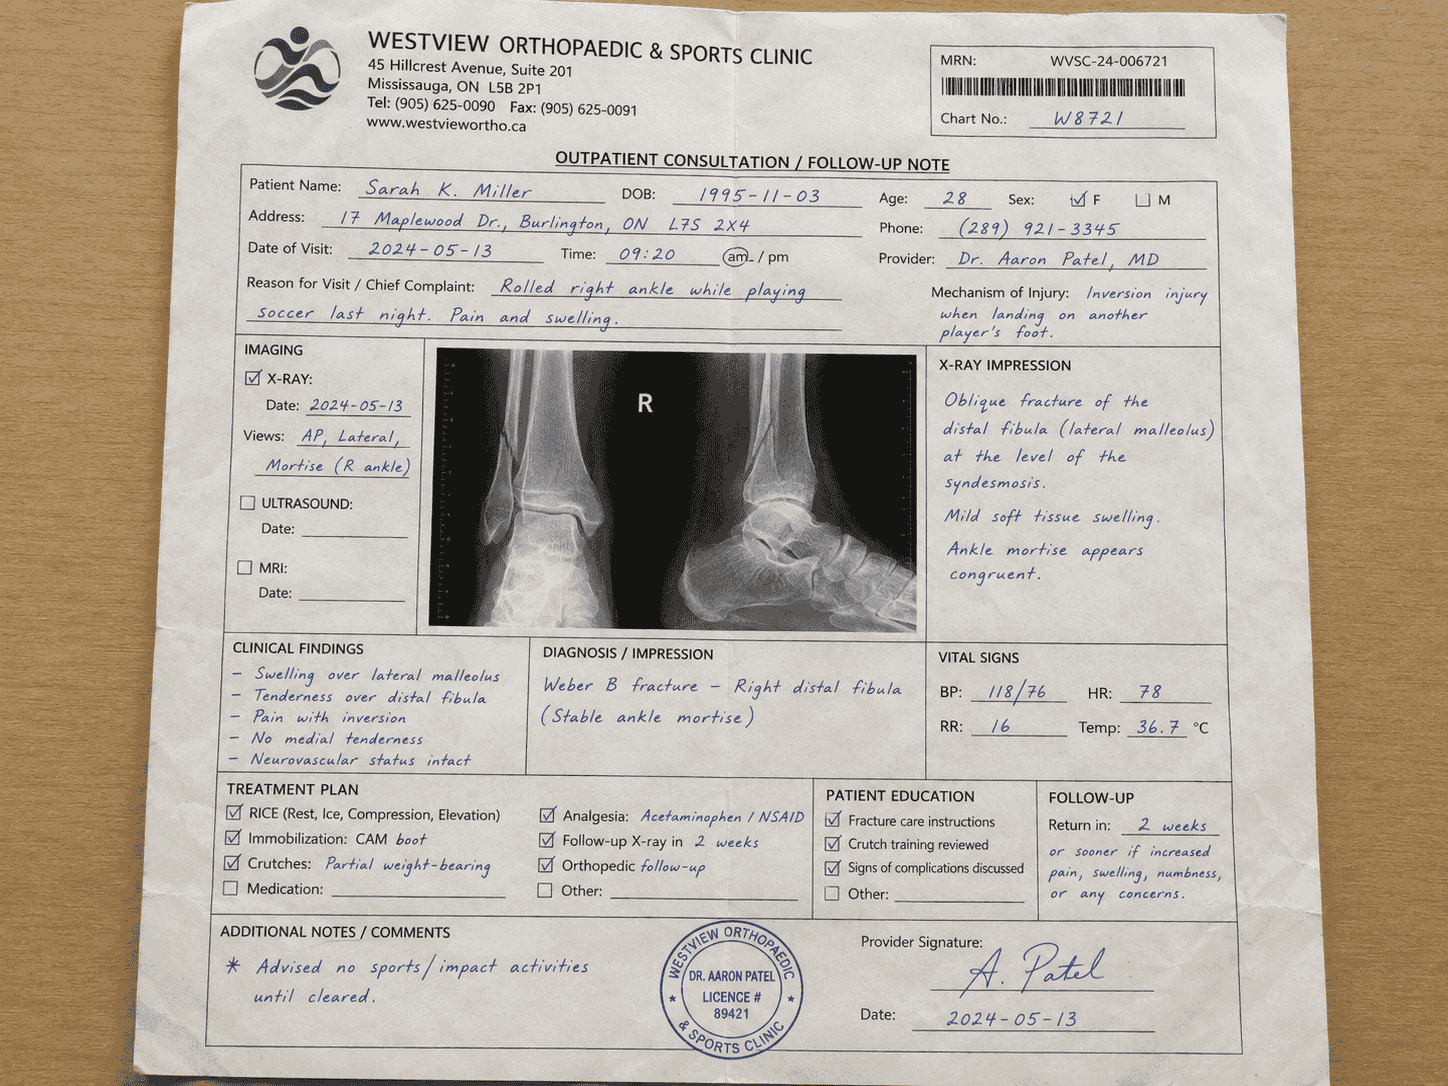
The note mixes print, handwriting, checkboxes, a stamp and a radiograph. One request has to read all of it and point to where each part is.
The code below does four things:
- Extracts the patient, X-ray, diagnosis and vitals into a schema. The injured side is an enum, so only
leftorrightcan come back. - Finds the X-ray and its side marker with object detection, and reads the marker's letter with OCR.
- Checks that the marker on the film matches the side written in the note. Wrong-side mistakes are a classic patient safety failure, so this runs on every note.
- Checks the identifiers and vitals against the OCR confidence of the line each came from. Fields at 0.9 or above post automatically, and the rest go to a nurse.
Interfaze SDK
Vercel AI SDK
LangChain SDK
import { Interfaze, responseFormat } from "interfaze";
import { z } from "zod";

const interfaze = new Interfaze({ apiKey: process.env.INTERFAZE_API_KEY });

const ConsultSchema = z.object({
	mrn: z.string(),
	patient_name: z.string(),
	date_of_birth: z.string(),
	visit_date: z.string(),
	side: z.enum(["left", "right"]),
	xray_views: z.array(z.string()),
	xray_impression: z.string(),
	diagnosis: z.string(),
	vitals: z.object({
		blood_pressure: z.string(),
		heart_rate: z.number(),
		respiratory_rate: z.number(),
		temperature_c: z.number(),
	}),
});

const response = await interfaze.chat.completions.create({
	model: "interfaze-1.1-lite",
	messages: [
		{
			role: "user",
			content: [
				{
					type: "text",
					text: "Extract the patient, X-ray, diagnosis and vitals from this consult note. Locate each X-ray view and its side marker.",
				},
				{ type: "image_url", image_url: { url: "https://r2public.jigsawstack.com/interfaze/examples/health_care_memo_example.png" } },
			],
		},
	],
	response_format: responseFormat(z.toJSONSchema(ConsultSchema), "consult_note"),
});

type Bounds = { top_left: { x: number; y: number }; bottom_right: { x: number; y: number } };
type OcrLine = { text: string; bounds: Bounds; average_confidence: number };
type Precontext = { name: string; result: { sections?: { lines: OcrLine[] }[]; detected_objects?: { label: string; bounds: Bounds }[] } }[];

const note = ConsultSchema.parse(JSON.parse(response.choices[0]?.message.content ?? "{}"));
const precontext = (response.precontext ?? []) as Precontext;

const lines = precontext.flatMap((p) => (p.name === "ocr" ? (p.result.sections ?? []) : [])).flatMap((s) => s.lines);
const films = precontext
	.flatMap((p) => (p.name === "object_detection" ? (p.result.detected_objects ?? []) : []))
	.filter((o) => o.label.toLowerCase().includes("x-ray"));

const inside = (inner: Bounds, outer: Bounds) =>
	inner.top_left.x >= outer.top_left.x &&
	inner.top_left.y >= outer.top_left.y &&
	inner.bottom_right.x <= outer.bottom_right.x &&
	inner.bottom_right.y <= outer.bottom_right.y;

const marker = lines.find((l) => /^[LR]$/.test(l.text) && films.some((f) => inside(l.bounds, f.bounds)));
const markerSide = marker?.text === "R" ? "right" : marker?.text === "L" ? "left" : undefined;
console.log(markerSide === note.side ? "auto" : "review", "side", note.side, marker?.text);

const REVIEW_BELOW = 0.9;

const fields = {
	mrn: note.mrn,
	patient_name: note.patient_name,
	date_of_birth: note.date_of_birth,
	blood_pressure: note.vitals.blood_pressure,
	heart_rate: String(note.vitals.heart_rate),
	respiratory_rate: String(note.vitals.respiratory_rate),
	temperature_c: String(note.vitals.temperature_c),
};

for (const [field, value] of Object.entries(fields)) {
	const confidence = lines.find((l) => l.text.includes(value))?.average_confidence ?? 0;
	console.log(confidence >= REVIEW_BELOW ? "auto" : "review", field, value, confidence);
}
The output
In our run on Interfaze 1.1 Lite, the schema response copied the handwriting, the X-ray impression and the diagnosis word for word:
{
  "mrn": "WVSC-24-006721",
  "patient_name": "Sarah K. Miller",
  "date_of_birth": "1995-11-03",
  "visit_date": "2024-05-13",
  "side": "right",
  "xray_views": ["AP", "Lateral", "Mortise"],
  "xray_impression": "Oblique fracture of the distal fibula (lateral malleolus) at the level of the syndesmosis. Mild soft tissue swelling. Ankle mortise appears congruent.",
  "diagnosis": "Weber B fracture - Right distal fibula (Stable ankle mortise)",
  "vitals": {
    "blood_pressure": "118/76",
    "heart_rate": 78,
    "respiratory_rate": 16,
    "temperature_c": 36.7
  }
}
Here's the precontext behind it, trimmed to the X-ray, its side marker and the heart rate line, without the outlines and per-word boxes:
[
  {
    "name": "object_detection",
    "result": {
      "detected_objects": [
        {
          "label": "X-ray image",
          "bounds": { "top_left": { "x": 420, "y": 367 }, "bottom_right": { "x": 934, "y": 624 }, "width": 514, "height": 257 }
        },
        {
          "label": "side marker",
          "bounds": { "top_left": { "x": 628, "y": 386 }, "bottom_right": { "x": 663, "y": 418 }, "width": 35, "height": 32 }
        }
      ]
    }
  },
  {
    "name": "ocr",
    "result": {
      "sections": [
        {
          "lines": [
            {
              "text": "R",
              "bounds": { "top_left": { "x": 634, "y": 388 }, "bottom_right": { "x": 656, "y": 415 } },
              "average_confidence": 1
            },
            {
              "text": "HR: 78",
              "bounds": { "top_left": { "x": 1080, "y": 678 }, "bottom_right": { "x": 1166, "y": 704 } },
              "average_confidence": 0.87
            }
          ]
        }
      ],
      "width": 1448,
      "height": 1086
    }
  }
]
And the checks print:
auto side right R
auto mrn WVSC-24-006721 1
auto patient_name Sarah K. Miller 1
auto date_of_birth 1995-11-03 1
auto blood_pressure 118/76 0.93
review heart_rate 78 0.87
review respiratory_rate 16 0.88
auto temperature_c 36.7 0.91
On the note itself, the X-ray is boxed in blue and its side marker in purple. Green fields post on their own, and red fields go to review.
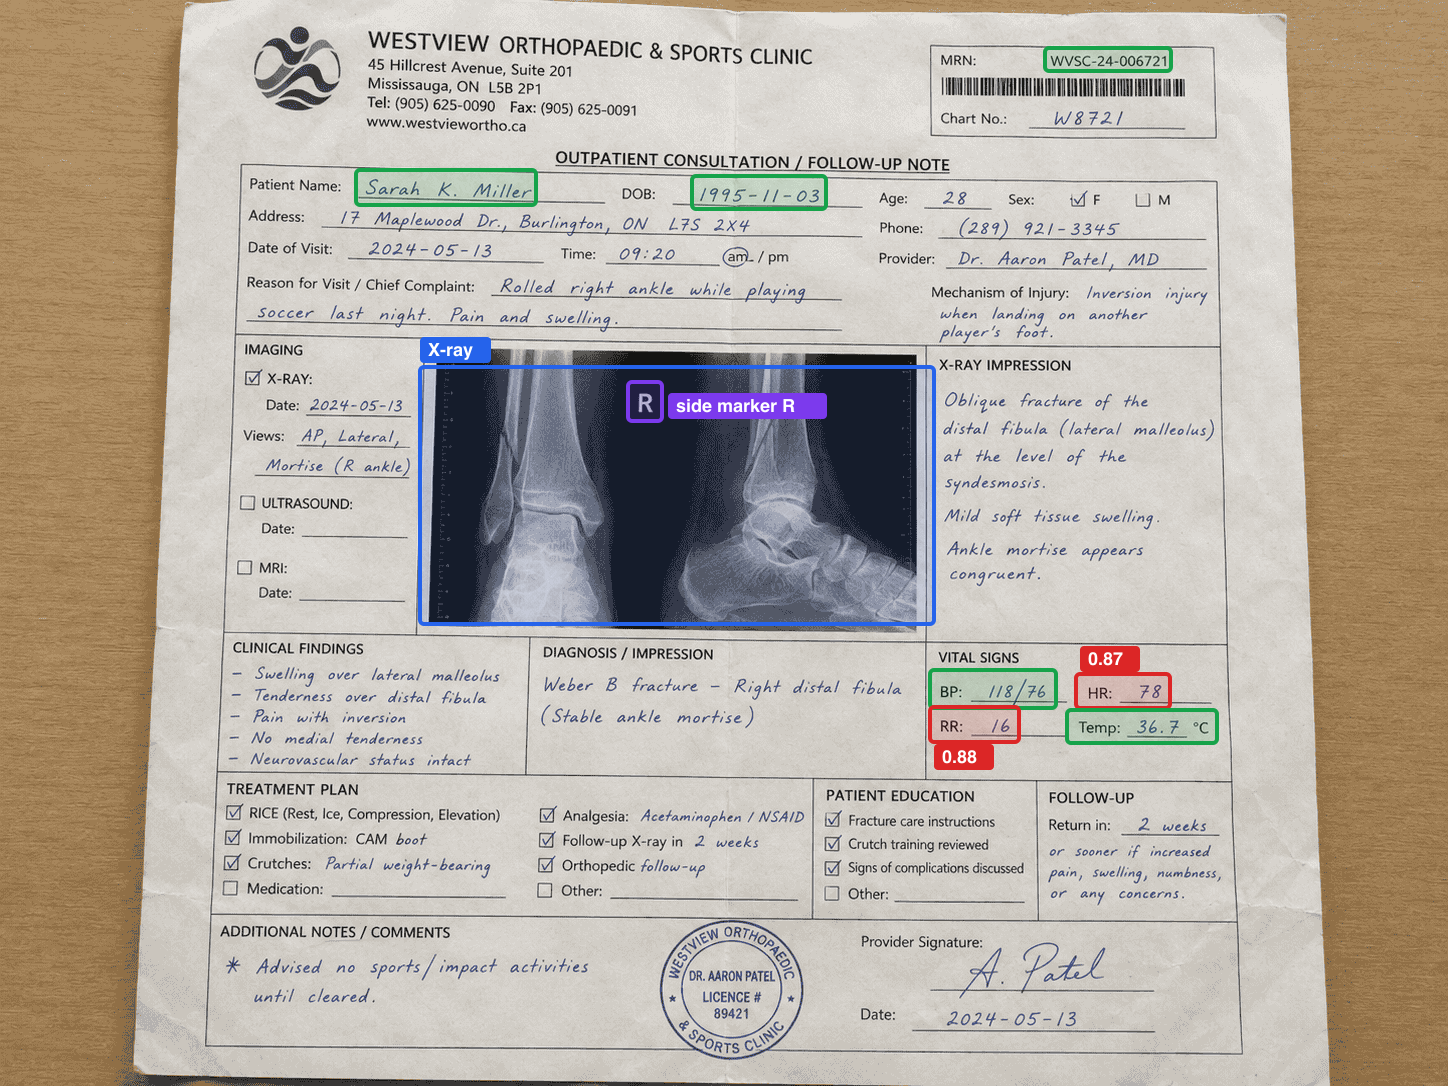
The side check passes. Object detection found the X-ray, and OCR read an "R" inside it at 1.0, which matches the right in the note.
The handwritten heart rate read at 0.87 and the respiratory rate at 0.88, so both go to a nurse. Both values were right, and the boxes show the reviewer exactly where to look.
A chat model could have returned the same JSON, but you'd have no way to tell which vital was shaky or whether the film matched the note.